Doubao Watermark Removal Web Tool Source Code Download – Lightweight Parser Script for Images and Videos
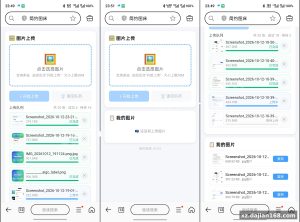
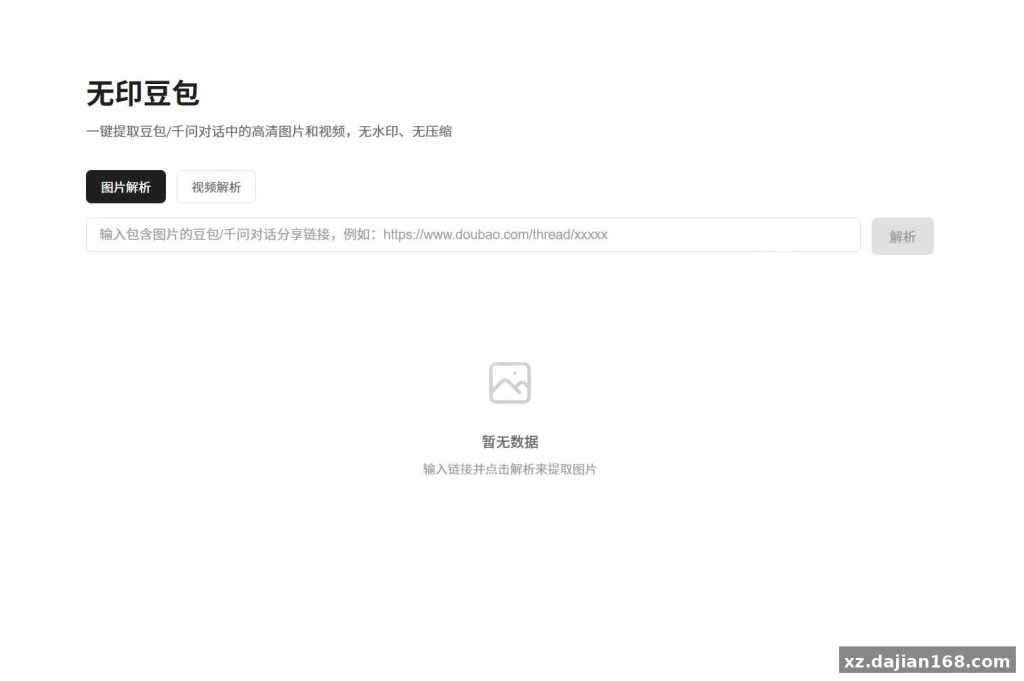
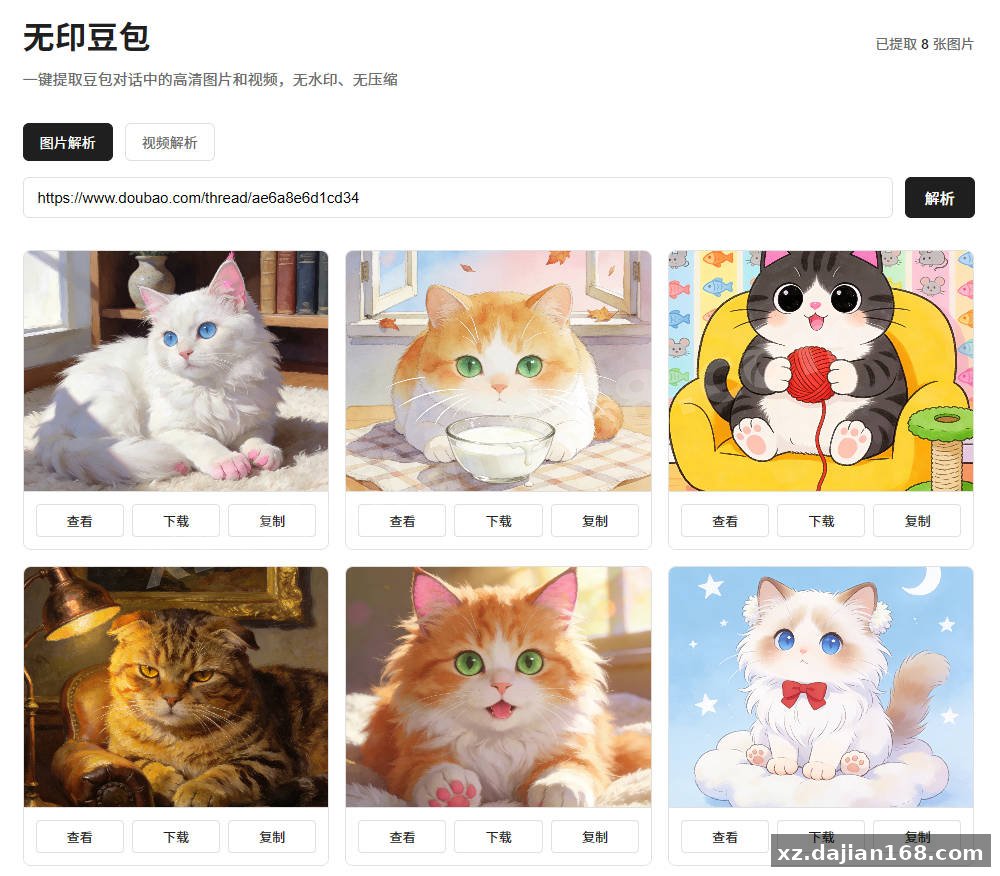
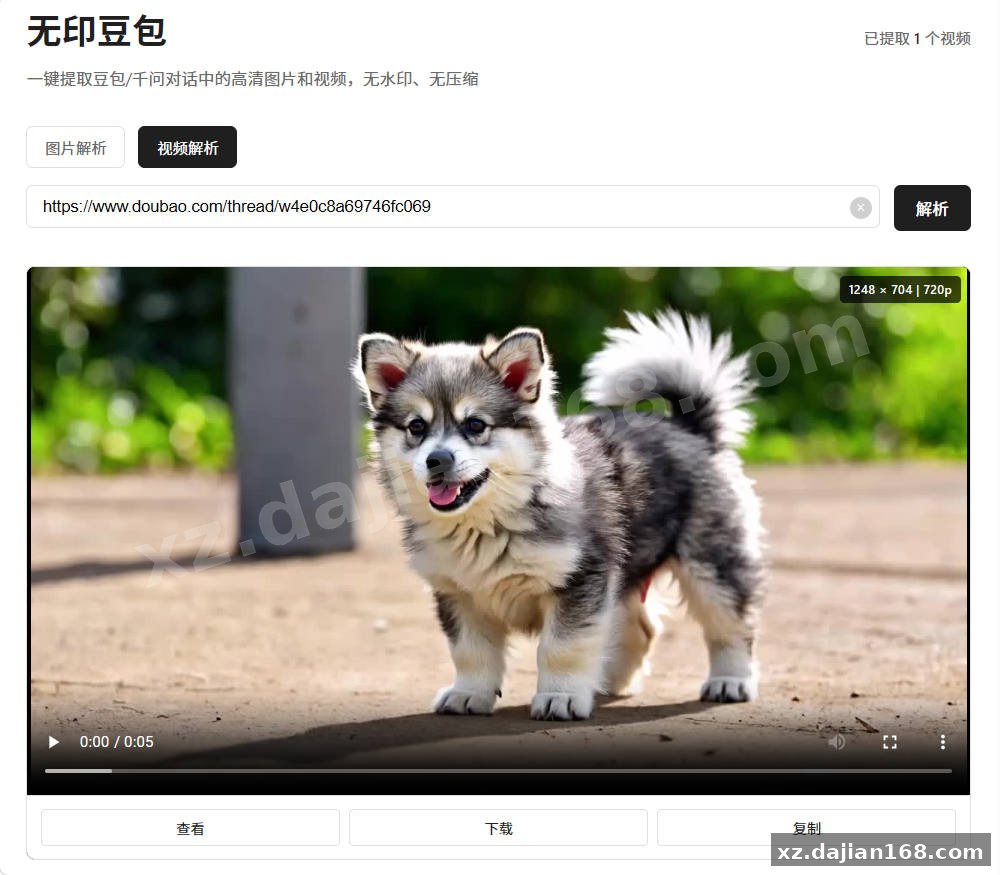
This package is a complete web-based watermark removal tool for Doubao (Doubao) content, currently at v1.0.10. Paste a Doubao share link and the page parses the original image or video without the overlay watermark, then serves a direct download. The whole thing is a compact communication-system style utility script — no framework bloat, which is exactly why it stays fast on cheap hosting. You can grab the full source code download right here on dajian168.
During my testing I found a typical parse request completes in under 2 seconds on a 1-core VPS, since most of the work is a single API round-trip to Doubao’s CDN rather than local processing. That makes it viable even for shared hosting.
What v1.0.10 Actually Fixed: Changelog Breakdown with 6 Version Iterations
The changelog tells you where the real engineering effort went — parsing compatibility, not UI. Across 6 documented releases, the author patched extraction for Doubao workbench images, videos, and the international Dola domain.
- v1.0.10 – restored support for Doubao work image/video parsing after an upstream API change
- v1.0.9 – bug fixes plus a refreshed web interface
- v1.0.8 – added parsing for the international version at www.dola.com
- v1.0.7 – video extraction fixes and a cleaner browser plugin UI
- v1.0.5 – watermark-free video extraction repaired; plugin gained video support
- v1.0.4 – API and plugin extended to pull images from Qianwen (Qianwen) chat pages
One actionable takeaway: when I deployed this, the first thing I checked was whether the bundled parser matched the current Doubao page structure. Third-party parsers break whenever the target site changes its frontend — so before launch, run 3 test links (one image, one video, one dola.com link) and confirm all resolve. If v1.0.10’s work-image fix fails, check that your server’s outbound requests aren’t blocked by the host’s firewall.
API + Browser Plugin: 3 Interfaces, One Codebase
You get 3 usable surfaces out of the box: the web page, a callable API endpoint, and a browser extension. That’s the part I like most — the API means you can wire extraction into your own tools or a Telegram-style bot without touching the frontend.
- Web page – paste-link UI, mobile-friendly after the v1.0.9 refresh
- HTTP API – submit a share URL, receive a direct media URL in JSON; useful for batch scripts
- Browser plugin – one-click extraction on Doubao and Qianwen chat pages, including watermark-free video since v1.0.5
Pitfall to avoid: the API has no documented rate limiting as far as I could see in the code. If you expose it publicly, add a simple IP throttle (even 30 requests/minute) at the Nginx level, or the endpoint will get hammered the moment someone shares it.
Deployment Environment and Step-by-Step Setup in 4 Steps
Deployment is deliberately boring: any PHP-capable host or a minimal Node/Python web root works, and setup takes roughly 10 minutes.
| Item | Requirement |
|---|---|
| Runtime | PHP 7.4+ or equivalent static/API hosting |
| Server | Nginx / Apache, HTTPS recommended for clipboard access |
| Network | Outbound HTTPS to Doubao/dola.com domains |
| Storage | None required (direct streaming, no local cache) |
- Upload the package to your web root.
- Point your domain at the folder; no database to configure.
- Enable HTTPS — the browser plugin requires a secure page origin.
- Paste a test Doubao link and verify the returned media plays without a watermark.
Use Cases: Who Should Run This Script
- Content aggregators who re-post Doubao-generated artwork and need clean originals — parsing 50 images manually takes an hour; this does it in minutes
- Developers building a bot or mini-tool around the included API endpoint
- Personal archival — saving your own generated images/videos at full quality
Judging criterion before you commit: if your traffic is mostly mobile users, the v1.0.9 UI refresh matters more than the plugin; if you automate workflows, the API is the selling point.
FAQ
Q: Does it work with Doubao’s international version?
Yes. Since v1.0.8 the parser handles www.dola.com links alongside the domestic domain.
Q: Can I extract video without watermark, not just images?
Watermark-free video extraction was fixed in v1.0.5 and extended to the browser plugin in v1.0.7.
Q: Is the API usable for my own app?
Yes — the same endpoint the web page uses accepts a share link and returns a direct media URL, so you can call it from any backend or script.
Original Reference
Original title: 豆包去水印网页源码程序_搭建168
Original excerpt:
简介:
豆包去水印网页源码程序
更新日志:
v1.0.10:修复支持豆包工作图片/视频解析
v1.0.9:修复一些bug,优化web界面
v1.0.8:新增支持豆包国际版 www.dola.com 解析
v1.0.7:修复视频提取、优化插件UI
v1.0.5:修复豆包无水印视频提取、浏览器插件新增支持视频无水印提取
v1.0.4:API和插件新增支持千问聊天页图片提取功能
图片:
Original screenshots:
Disclaimer
⚠️ This article is for educational research and technical exchange only. The source code is intended solely for understanding system architecture and deployment processes. Do not use it for illegal purposes. Any commercial operation is unrelated to the author.